One view of service health
Bring approved monitoring, logs and service information together. Connect related alerts to the application or business service they may affect, so teams have a clearer place to start.
Connect infrastructure monitoring, application signals and operational knowledge so your team can investigate issues, plan capacity and approve the right response.
When an application slows down, your team needs more than another alert. We connect the available signals from your servers, cloud services, networks and applications, then use AI to organise the evidence and suggest the next investigation. Start with the tools you already use and an agreed service scope, whether your environment is on-premise, cloud or hybrid.
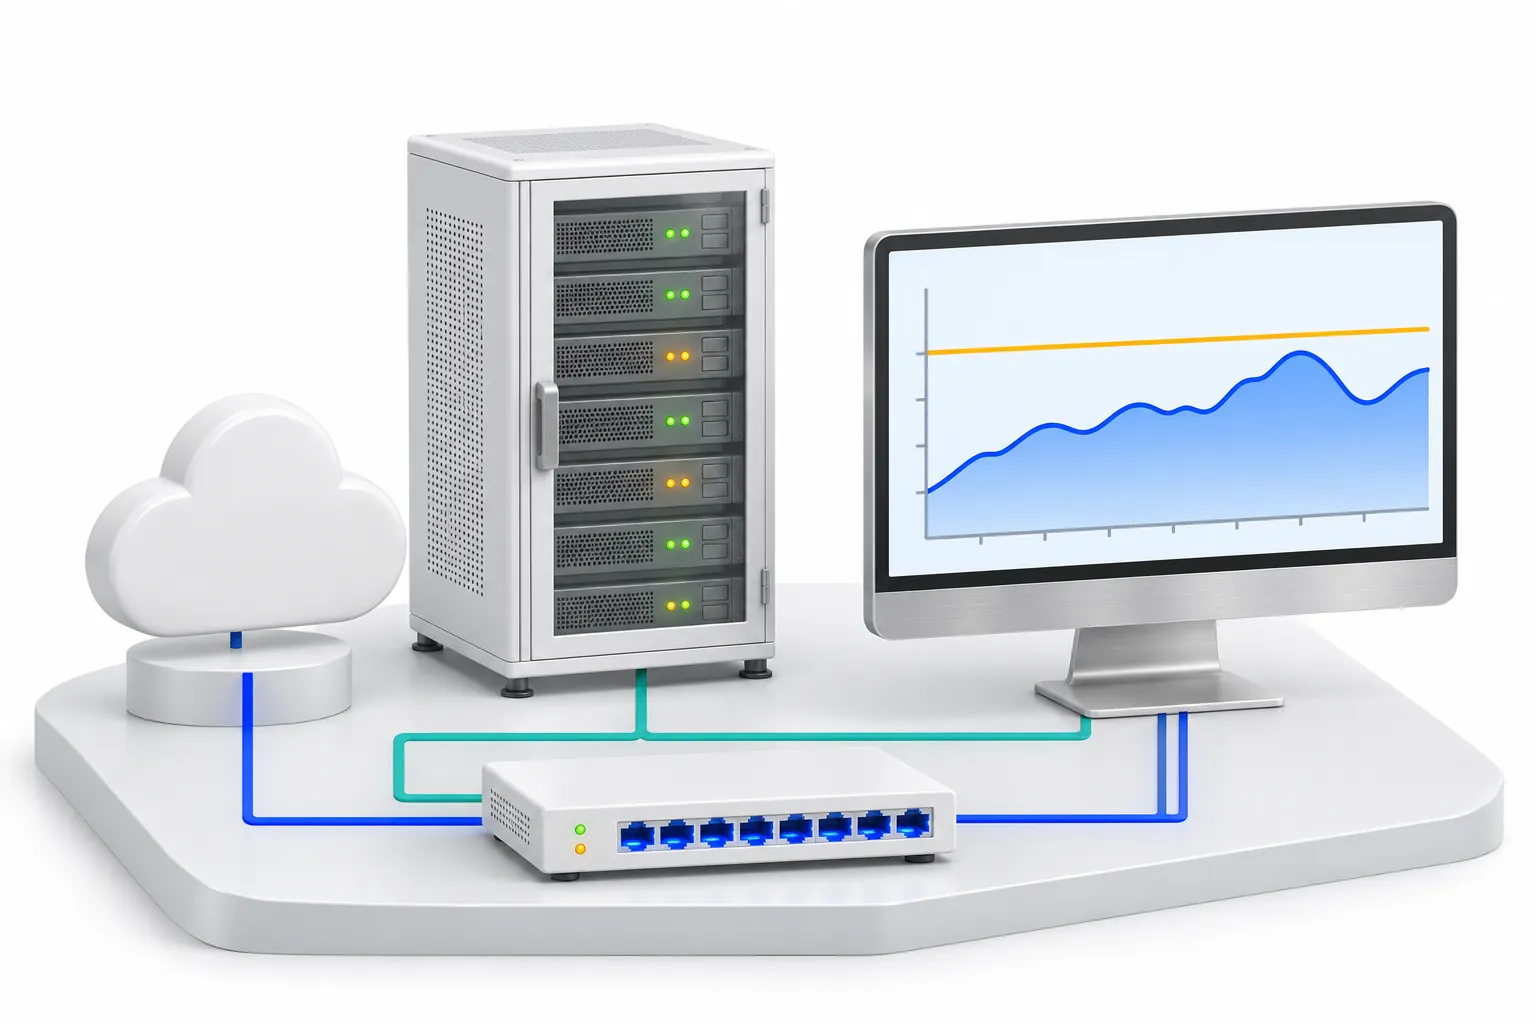
Signals from cloud services, servers and network devices come together, so issues and capacity limits are visible before they disrupt work.
Bring approved monitoring, logs and service information together. Connect related alerts to the application or business service they may affect, so teams have a clearer place to start.
Highlight unusual behaviour and gather relevant events, recent changes and runbooks. Present likely causes as investigation leads with supporting evidence, rather than treating a prediction as a confirmed diagnosis.
Review resource usage, storage growth and available billing data. Surface underused capacity or changing demand and prepare recommendations for your team to assess against service needs.
Create a ticket, prepare a recovery checklist or propose a permitted runbook action. Keep sensitive changes behind approval, with scoped access, activity history and a recovery plan.
Your ordering application becomes slow while database storage is filling. The workflow brings the related alerts and recent changes into one investigation, shows the services that may be affected and prepares a response for the infrastructure team to review. A change is carried out only through the agreed permissions and approval process.
The starting scope can be read-only monitoring and recommendations. Any operational action is agreed separately, limited to approved runbooks and tested before use. Changes such as restarting a service, adjusting capacity or changing configuration can require human approval, with a recorded result and a recovery procedure.
Not sure this is the right starting point? Use the solution finder or browse all solutions.
Tell us about your workflow, the systems you use and the problem you want to solve.